3 October 2026 · Agentic game · browser FPS
Whiteout Protocol · GPT-6 Luna
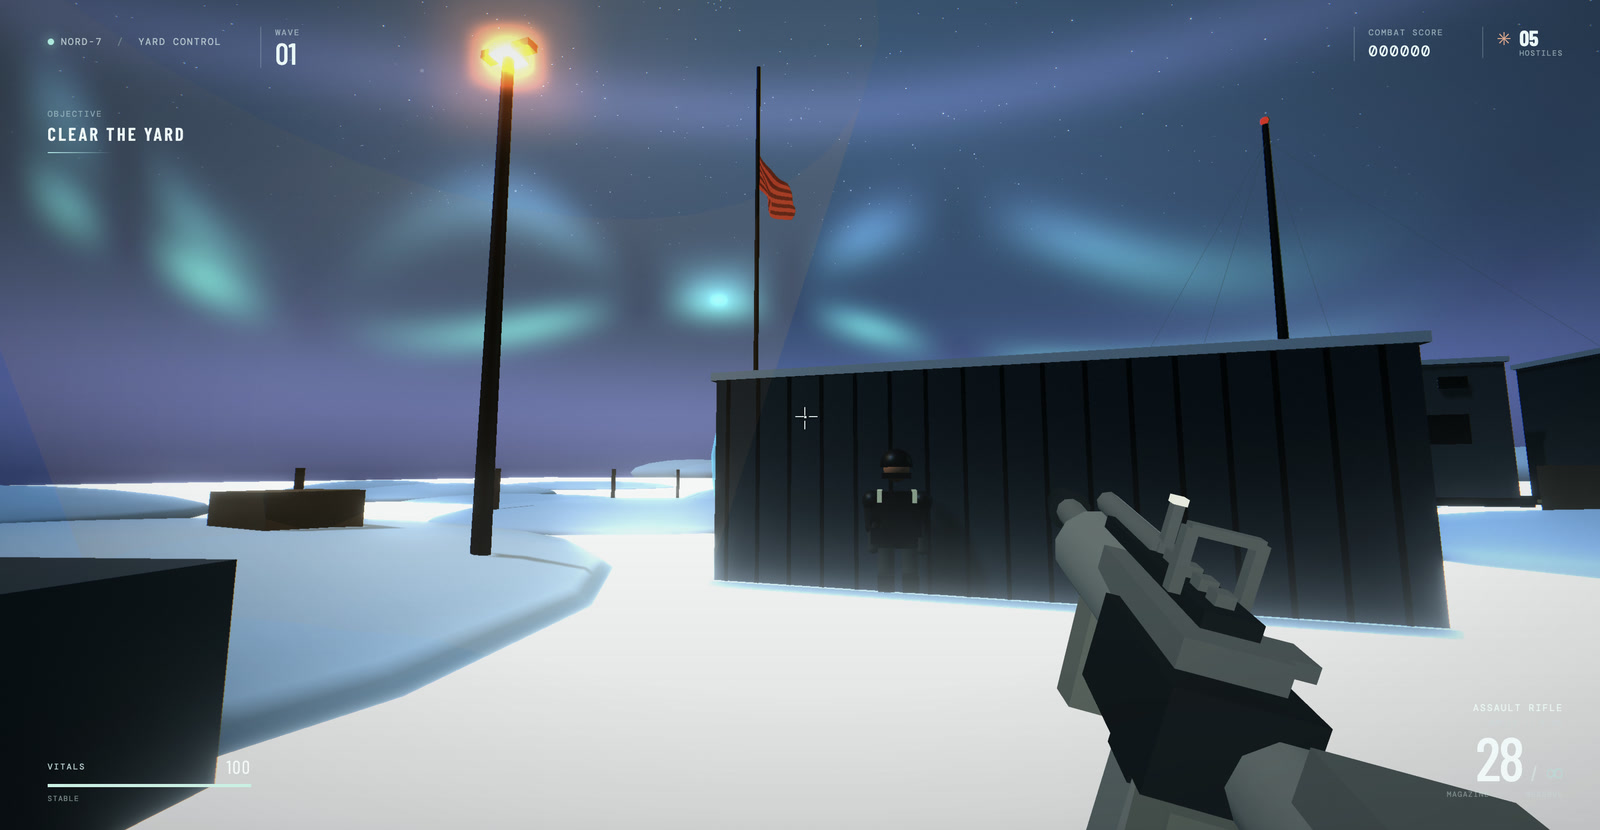
Codex completed the one-shot task and produced a static Whiteout Protocol browser FPS build. No independent gameplay acceptance score is assigned.
What was checked
- The Codex session log records a successful Vite production build; its emitted bundle filenames match the archived static artifact.
Limits of this evidence
The public record excludes the original prompt, Codex transcript, session log, session identifier, local source paths, and tool arguments/results. Cached input is a subset of cumulative input; reasoning output is a subset of output.
Configuration
The model, serving engine and agent used for this execution.
| Field | Value | Detail |
|---|---|---|
| Model · cloud_baseline | GPT-6 Luna · cloud_baseline · reasoning xhigh | — |
| Runtime | OpenAI hosted inference Provider-managed service; exact build not exposed | inference engine and exact build |
| Harness | OpenAI Codex | the agent or client that drove the run |
| Hardware | Provider-managed cloud inference; physical host not disclosed | hardware recorded for this execution |
| Workload | Whiteout Protocol · revision 1 | One-shot coding challenge. The prompt file was byte-identical to the local Sushi Whiteout run; the original prompt is excluded from this archive. |
| Repetitions | 1 | executions recorded for this workload; one means an indicative result, not an estimate |
Agent session counters
Agent-wide usage totals. These include reasoning, tool calls and waiting, and are not model decode speed.
| Metric | Value | Definition |
|---|---|---|
| Task elapsed | 59.1 min | user request received to first task completion; includes reasoning, tools, and waiting · n=1 |
| End-to-end output rate | 42.14 tok/s | output_tokens divided by task_wall_time; includes reasoning, tool calls, and waiting; not model decode speed · n=1 |
Context and token counters
Token totals as reported by the harness or engine. Cached and cumulative figures are not additive with fresh input.
| Metric | Value | Definition |
|---|---|---|
| Cumulative input | 23,556,664 tokens | cumulative across model calls; repeated conversation context can be counted again · n=1 · Taken from the cumulative Codex usage snapshot immediately before task completion. |
| Cached input | 23,088,768 tokens | cumulative cached input; included in cumulative_input_tokens · n=1 |
| Output tokens | 149,405 tokens | cumulative across model calls; includes reasoning and tool output · n=1 |
| of which reasoning output | 77,698 tokens | subset of output_tokens · n=1 |
Request records & provenance
The retained metrics do not provide token emission timestamps or reliable time-to-first-token latency. The aggregate end-to-end output rate is not comparable to local per-request engine decode or prefill measurements.
Run ID: 2026-10-03-gpt-6-luna-codex-whiteout-protocol-baseline
One execution, with checks transcribed from the retained record. A completed session is not a quality score. Measurement method · All runs