10 October 2026 · Agentic game · 3D western action
Wild West Showdown 3D
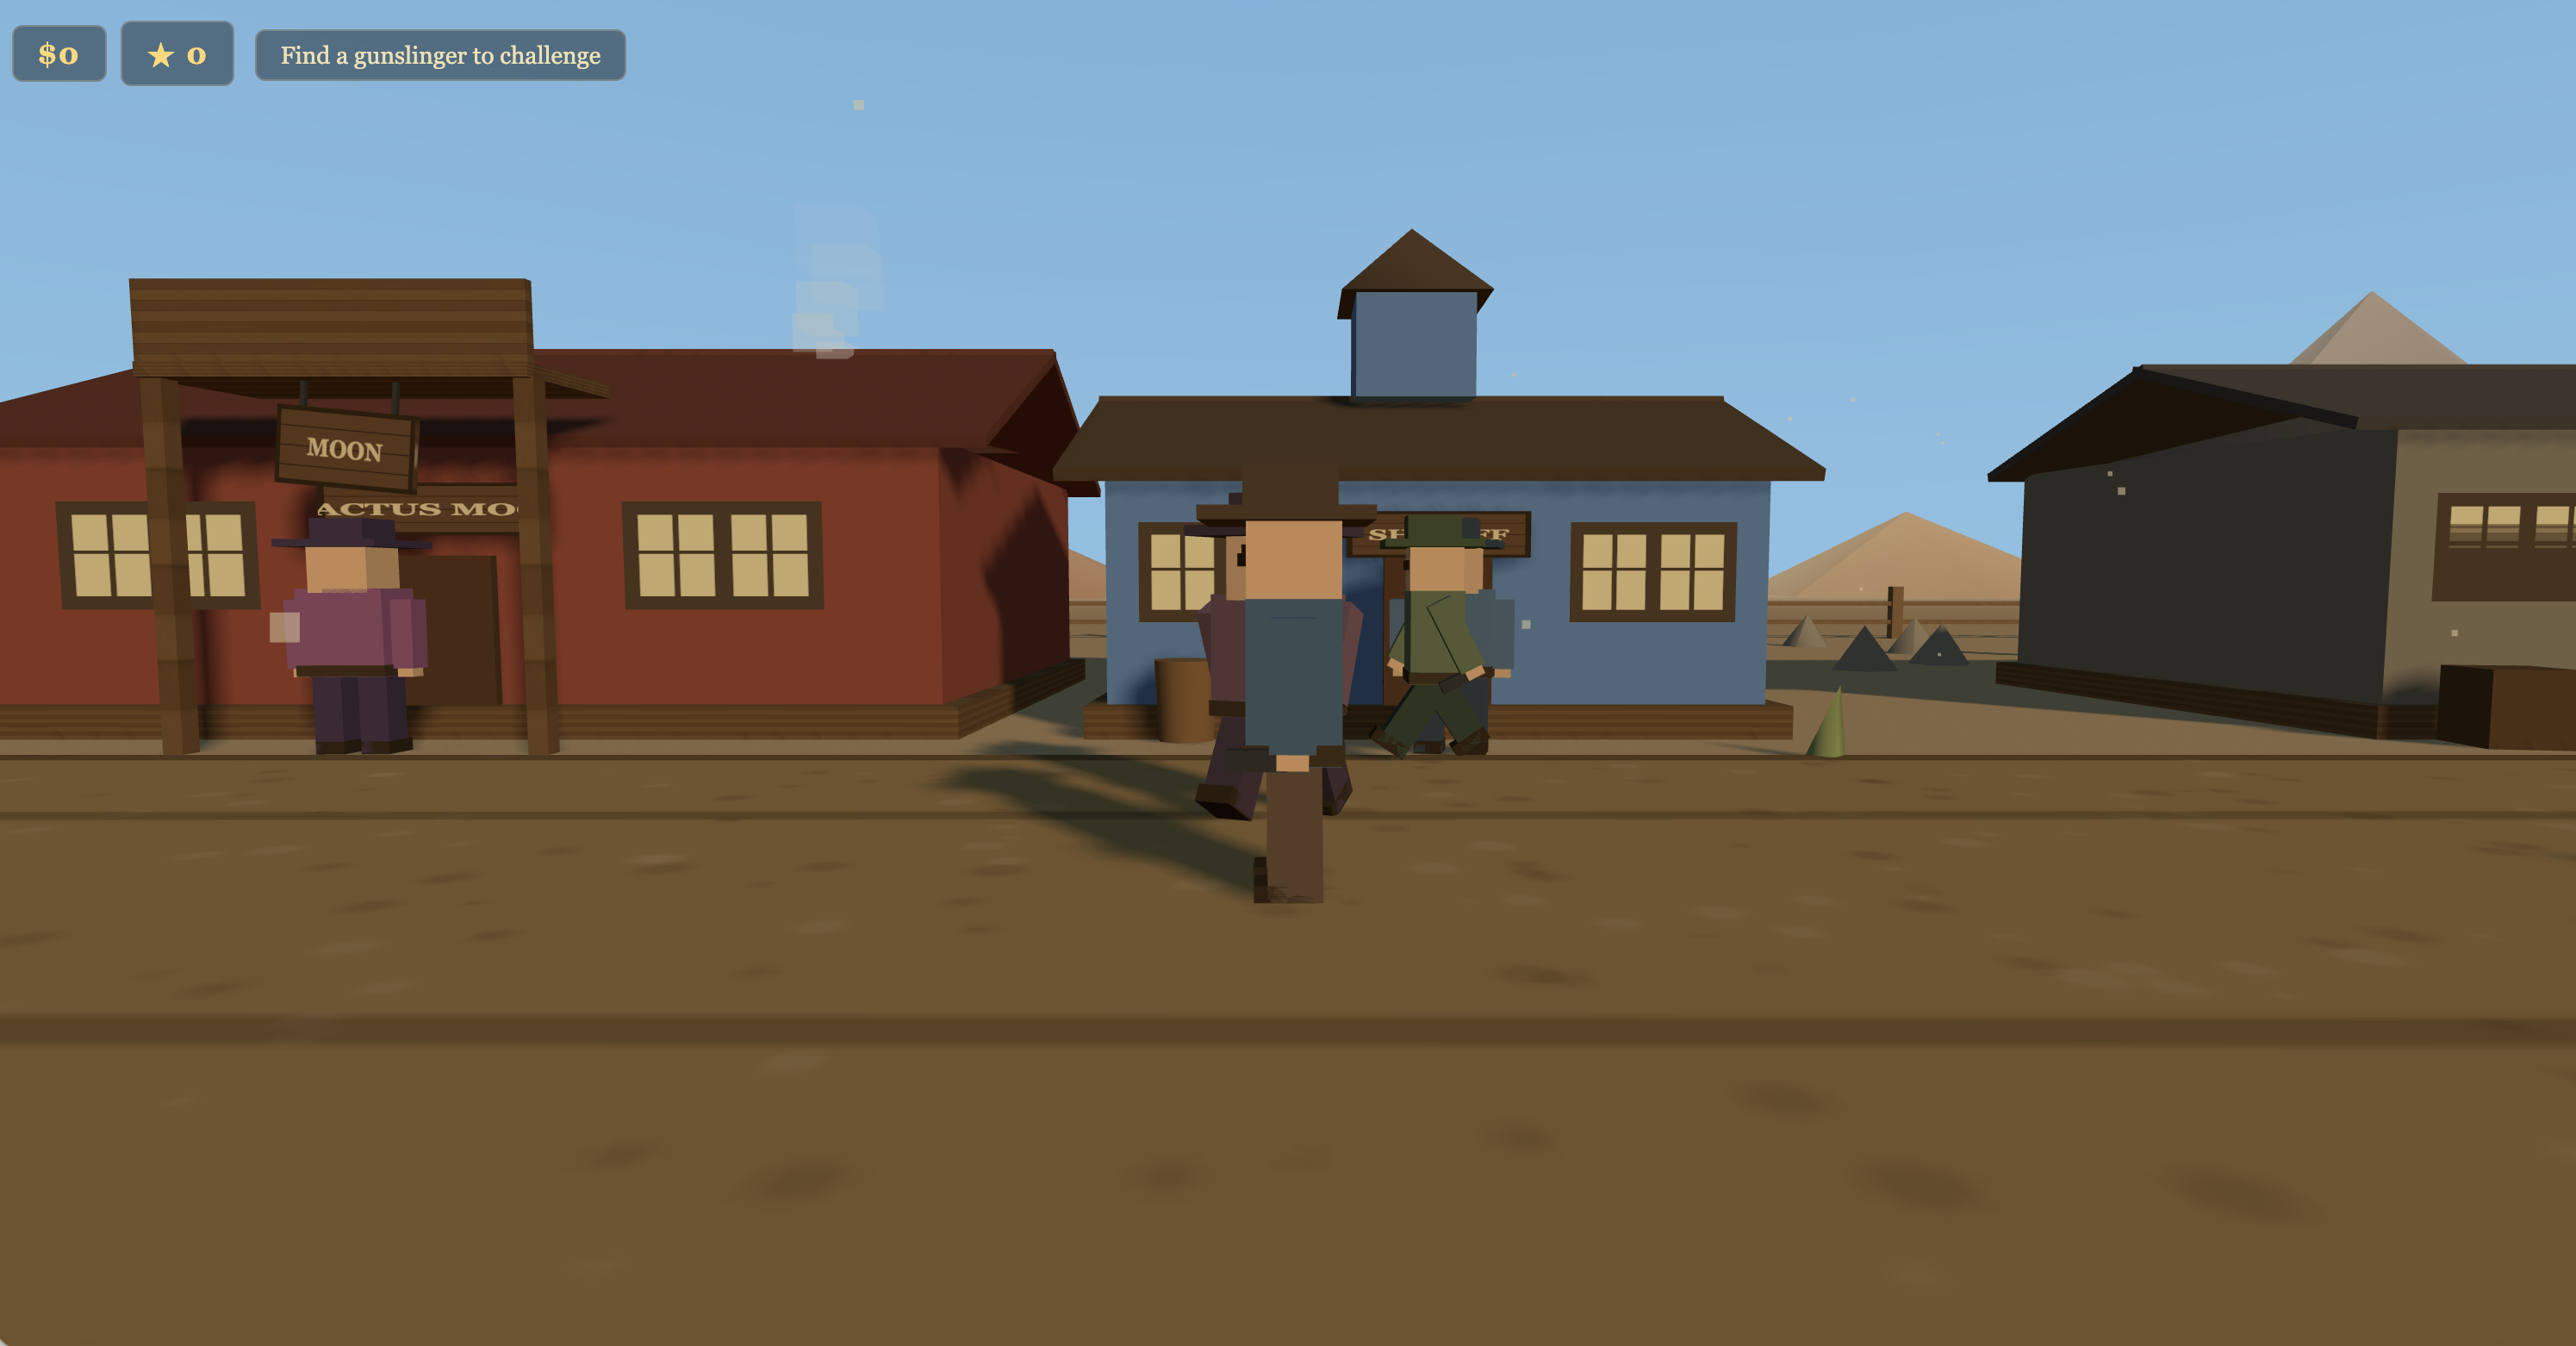
The playable game was completed after manual continuation. The deterministic runner stopped during M03 after two unsuccessful sessions, and its planned independent final review did not run.
What was checked
- The Architect phase created GAME_SPEC.md, a 12-milestone PLAN.md, STATE.md, DECISIONS.md and REVIEW.md before substantial implementation.
- M01 and M02 were completed in manual Pi sessions before the runner was installed; the runner ledger explicitly excludes their metrics.
- The runner attempted M03 twice. The first session recorded four provider errors and ended without settling; the second was manually terminated with exit code 143 after about 66 minutes.
- The user continued in later fresh Pi sessions. The final manual completion session used medium reasoning and has 186 successful Pi/TensorFold request matches, five failed model requests and two context compactions.
- The completed project was committed as a504f28f07d93ced782fff18223096d1d2787071. Its retained smoke report says 65/65 checks passed and records no open Critical findings.
- The retained REVIEW.md says READY FOR FINAL REVIEW. Real-device frame rate, tablet touch ergonomics and audible output were not verified, and the runner's independent final review did not run.
Limits of this evidence
This is not a clean autonomous benchmark run. The runner config recorded medium reasoning, but the two automatic M03 sessions reached TensorFold with thinking disabled and effort=none. The second session was manually terminated. Later sessions included setup failures and a manual continuation; this record publishes only the final completion session's usage metrics and does not pool counters across phases. The completed game artifact and runner outcome are separate: the game reached its final victory state in the reported smoke suite, while the planned independent runner review remained pending.
Configuration
The model, serving engine and agent used for this execution.
| Field | Value | Detail |
|---|---|---|
| Model · primary | Qwen 3.8 27B · primary · reasoning mixed across phases | MLX affine 4-bit, group size 64 · 4 bpw |
| Checkpoint · primary | TensorFold/Qwen3.8-27B-MLX-4bit | primary model artifact · revision 22d8d538154e0e5b6f8dcb1fcc74a60a0798104c |
| Model · drafter | Qwen 3.8 27B DFlash2 · drafter | Unquantized on disk |
| Checkpoint · drafter | z-lab/Qwen3.8-27B-DFlash2 | drafter model artifact · revision 50307d4c4cde6860d4eee73e2547cd786fe8e8a4 |
| Runtime | TensorFold native (Zig) 1.0.4 · Zig native | inference engine and exact build |
| Harness | Pi coding agent 1.1.0 | the agent or client that drove the run |
| Hardware | Apple MacBook Pro · 64 GB unified memory | hardware recorded for this execution |
| Workload | Wild West Showdown 3D · revision 1 | Staged long-horizon browser-game challenge with persistent planning and state files. This record is dated at the 10 October runner launch; manual planning began on 9 October. Manual continuation is part of the same attempt. |
| Context window | 131,072 tokens | maximum context configured for the serving runtime |
| Repetitions | 1 | executions recorded for this workload; one means an indicative result, not an estimate |
Agent session counters
Agent-wide usage totals. These include reasoning, tool calls and waiting, and are not model decode speed.
| Metric | Value | Definition |
|---|---|---|
| Session elapsed | 1891.3 min | Pi session start to final assistant response; includes tool execution and waiting. · n=1 · Final manual completion session only; spans 10 October 22:48 UTC to 12 October 06:19 UTC. Not a pooled task duration. |
| Model responses | 191 responses | Assistant responses with usage records in the final manual completion session, including failed requests. · n=1 |
| Matched model requests | 186 requests | Successful Pi responses matched monotonically and uniquely to native TensorFold summaries by prompt, output and cached-token counts. · n=1 · Final manual completion session only; unmatched engine summaries are excluded. |
| Model request errors | 5 errors | Failed model requests in the final manual completion session. · n=1 |
| Tool calls | 199 calls | Total Pi tool calls in the final manual completion session. · n=1 |
| Tool errors | 8 errors | Tool results marked as errors by Pi in the final manual completion session. · n=1 |
| Context compactions | 2 compactions | Pi context compactions in the final manual completion session. · n=1 |
Context and token counters
Token totals as reported by the harness or engine. Cached and cumulative figures are not additive with fresh input.
| Metric | Value | Definition |
|---|---|---|
| Maximum prompt context | 114,452 tokens | Largest Pi input plus cache-read count in the final manual completion session. · n=186 |
| Fresh input | 12,848,907 tokens | Sum of Pi uncached input counters in the final manual completion session. · n=1 |
| Cached input | 0 tokens | Sum of Pi cache-read counters in the final manual completion session. · n=1 |
| Cumulative input | 12,848,907 tokens | Fresh input plus cache-read tokens in the final manual completion session. · n=1 |
| Output tokens | 192,547 tokens | Pi output usage in the final manual completion session; includes reasoning tokens. · n=1 |
| of which reasoning output | 96,750 tokens | Pi-reported reasoning tokens included in output tokens, final manual completion session. · n=1 |
Request records & provenance
The final manual Pi session's successful request triples were matched in order against native TensorFold summaries. The published count excludes failed requests and unused engine summaries. Raw prompts, response text, request IDs, timestamps, hashes and server logs are not published.
Run ID: 2026-10-10-qwen38-27b-tensorfold-native-104-pi-wild-west-showdown-3d
One execution, with checks transcribed from the retained record. A completed session is not a quality score. Measurement method · All runs