12 October 2026 · Agentic task loop · interactive figure
Prefix Cache Anatomy
The orchestrator reached COMPLETE after 10 h 26 min of run time in three segments. All 14 model-planned tasks are done, the project's verify passes 35 checks in 103 s (limit 240 s), and the final reviewer accepted all 26 requirements. The model invented a paper-tape telegraph relay desk whose parts show prefix reuse, partial reuse, a miss, LRU eviction and refusal. 21 of 62 sessions ended on engine memory errors; none counted against a task.
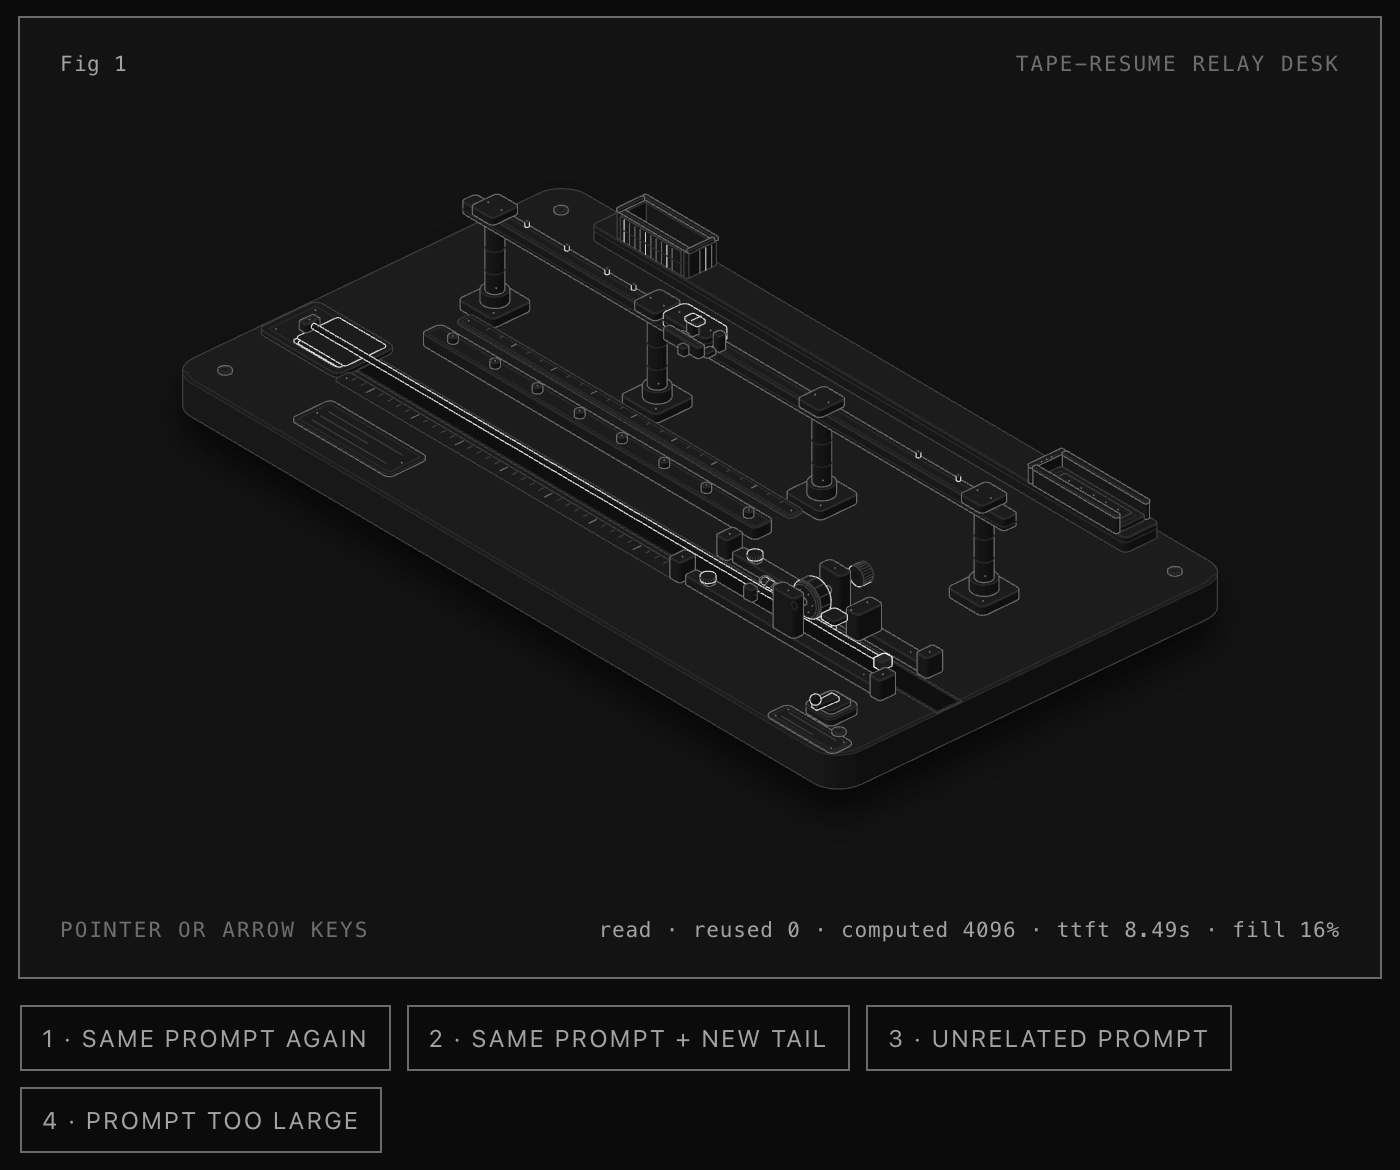
What was checked
- Bootstrap was accepted on its first session: 26 requirements, 14 task cards, full requirement coverage and a deterministic verify.
- Each task was accepted only after the orchestrator ran verify --all and verify --task <ID> and a fresh reviewer returned ACCEPT. Reviewers sent T004 and T007 back once and T008 twice.
- verify covers model.mjs behaviour, both page builds, headless-Chrome loads without console errors (the skill's capture.mjs), the skill's geometry audit, the line-end check (0 loose ends on both pages), and dark/light screenshots at 1440 px and 390 px plus one mid-motion frame.
- The final reviewer drove the pages itself: the four prompt cases by pointer and keys 1-4, the idle tour, pause offscreen, reduced motion, and readouts matching a Node replay of the model.
- Independent check after the run: verify --all passed 35/35 in 103 s; the screenshots are non-blank and show the machine and live readout; model.mjs was exercised outside the figure for reuse, partial reuse, miss, LRU eviction, oversized refusal and the 1.2 GB size of a 15,000-token state. One deviation: a full miss is charged the 0.3 s resume time on top of the prefill time.
Limits of this evidence
Run configuration changed between segments. Before the second segment the orchestrator gained a context cap driven by the engine's reported maximum, a large-tool-output steer, and a shared rule against reading large files whole (journal records templates-refreshed and orchestrator-changed). The cap never triggered, because every later engine error reported a maximum below the 32k floor. The generated project, transcripts and engine logs stay on the workstation.
Configuration
The model, serving engine and agent used for this execution.
| Field | Value | Detail |
|---|---|---|
| Model · primary | Qwen 3.8 Flash Next · primary · reasoning medium | EXL3 2.625 bpw (K=2.625; MCG codebook, window 15), confirmed by the Sushi 1.2.2 startup log |
| Checkpoint · primary | Qwen3.8-Flash-Next-Sushi-2.6bpw | primary model artifact |
| Runtime | Sushi 1.2.2 · OpenAI-compatible server, one process for the whole run, greedy sampling, MTP drafts, 8-bit KV cache, SSD prefix cache, vision on, /metrics enabled mode | inference engine and exact build |
| Harness | Pi coding agent, driven by the task-loop orchestrator, with the anatomy skill 1.1.0 | the agent or client that drove the run |
| Hardware | Apple MacBook Pro · 64 GB unified memory | hardware recorded for this execution |
| Workload | Prefix Cache Anatomy · revision 1 | Second run of the task-loop orchestrator (scripts/task-loop.mjs), and the first with a visual, open-ended brief: an interactive isometric figure that explains an LLM server's prefix cache, built with the anatomy skill loaded in every session. The orchestrator ran 62 fresh Pi sessions with no human input to the model. The run blocked twice on engine memory and was resumed with --resume after the operator freed memory. |
| Context window | 131,072 tokens | maximum context configured for the serving runtime |
| Repetitions | 1 | executions recorded for this workload; one means an indicative result, not an estimate |
Inference measurements
Engine-side rates for this run. Each figure states its own statistic; figures from different runs are not interchangeable.
| Metric | Value | Definition |
|---|---|---|
| TTFT · median | 3.064 s | Median engine-measured TTFT from Sushi /metrics deltas around each response (p90 19.18 s). · n=871 |
| Decode · output-weighted | 40.14 tok/s | Output tokens / engine decode seconds over requests with engine timings (output-weighted). · n=871 |
| Draft acceptance | 63.01 % | Accepted MTP draft tokens / drafted tokens from Sushi spec-stats over matched requests. · n=872 · 346605 accepted of 550069 drafted. |
| Swapped in during the run | 197.86 GiB | Pages swapped in during the run (vm_stat Swapins deltas, 16 KiB pages) over 1350 samples at 30 s and session boundaries. · n=1350 · Kernel memory pressure reached warning in 129 samples and never critical. |
Agent session counters
Agent-wide usage totals. These include reasoning, tool calls and waiting, and are not model decode speed.
| Metric | Value | Definition |
|---|---|---|
| Run elapsed | 626.5 min | Sum of the three run segments (start or --resume to COMPLETE or BLOCKED): 4 h 55 min, 1 h 9 min and 4 h 23 min. Excludes the time the run sat BLOCKED; includes 103 min of engine-retry backoff. · n=1 |
| Agent sessions | 62 sessions | Fresh Pi sessions started by the orchestrator: 1 bootstrap, 40 builder, 18 reviewer, 2 replan, 1 final reviewer. · n=1 |
| Sessions ended by engine errors | 21 sessions | Sessions that ended with a Sushi 400 error because the prompt needed more GPU memory than was available. Rerun without counting as task attempts. · n=1 · 14 in the first segment (large contexts on a nearly full machine), 7 in the second (a 5-7 GB browser was open). None in the third, after the operator closed other applications. |
| Model responses | 898 responses | Assistant responses with usage records across all sessions, including 26 error responses. · n=1 |
| Matched model requests | 872 requests | Successful Pi responses matched in order to Sushi 1.2.2 request summaries by prompt total, output tokens and cached (SSD-restored) tokens. · n=1 · All 872 matched in one process log (PID 97969). 17 key tuples occur more than once because rerun sessions replayed identical first turns under greedy decoding; each repeat appears once per session in the same order, so the ordered assignment is forced. 22 engine summaries are left unassigned: preflight probes, the deleted first launch, and two unrelated requests. |
| Tool calls | 1,099 calls | Pi tool calls across all sessions. · n=1 |
| Context compactions | 1 compactions | Pi context compactions across all sessions (T006, session 037). · n=1 |
Context and token counters
Token totals as reported by the harness or engine. Cached and cumulative figures are not additive with fresh input.
| Metric | Value | Definition |
|---|---|---|
| Maximum prompt context | 113,626 tokens | Largest engine-reported prompt among matched requests. · n=872 |
| Fresh input | 4,001,102 tokens | Sum of Pi uncached input counters across all sessions. · n=1 |
| Cached input | 25,155,774 tokens | Sum of Pi cache-read counters; equals Sushi's cached counts for the matched requests. · n=1 |
| Prompt-cache token share | 86.28 % | Cached input tokens / prompt tokens over matched requests (25,155,774 / 29,156,876). · n=872 |
| Output tokens | 807,277 tokens | Pi output usage across all sessions; includes reasoning tokens. · n=1 |
| of which reasoning output | 584,641 tokens | Pi-reported reasoning tokens included in output tokens. · n=1 |
Recorded check counters
Counts from the checks recorded with this run.
| Metric | Value | Definition |
|---|---|---|
| Tasks completed | 14 tasks | Task cards with status done at the end; none split, blocked or dropped. · n=1 |
| Reviews returning changes | 4 reviews | Reviewer sessions that returned CHANGES. · n=1 |
| Project checks passing | 35 checks | Checks passed by the project's own ./verify --all at the end (103 s). · n=1 |
| Hidden acceptance cases passed | 8 checks | Hidden acceptance cases passed, of 10: written from the brief, never shown to the model, and scored the same way for every run. Added after the run. · n=1 · Failed miss.cold and miss.unrelated, one defect: a prompt with no stored match is charged the 0.3 s resume time on top of prefill. |
Request records & provenance
Per-request numbers are not published. All 872 successful Pi responses were matched in order to the Sushi 1.2.2 process log (prompt total, output and cached tokens). TTFT and decode come from Sushi /metrics counters read before and after each response; 871 responses had exactly one finished engine request with token counts equal to Pi's.
Run ID: 2026-10-12-qwen38-flash-next-sushi-v122-pi-task-loop-anatomy-prefix-cache
One execution, with checks transcribed from the retained record. A completed session is not a quality score. Measurement method · All runs