Local Model Benchmarks

Local test machine: Apple M5 Pro · 64 GB unified memoryRun window 29 September — 18 October 202622 recorded runs

Workload · Task-loop orchestrator · video edit · Revision 1

Local Model Benchmarks Promo

A 30-second vertical promo for this site, edited with HyperFrames from an approved six-scene storyboard, the site's own design system and a locally made asset pack. It follows Custom Characters Promo with a much fuller brief, to see how much of the gap to a crafted render the instructions close.

1 recorded attempt

Recorded attempt

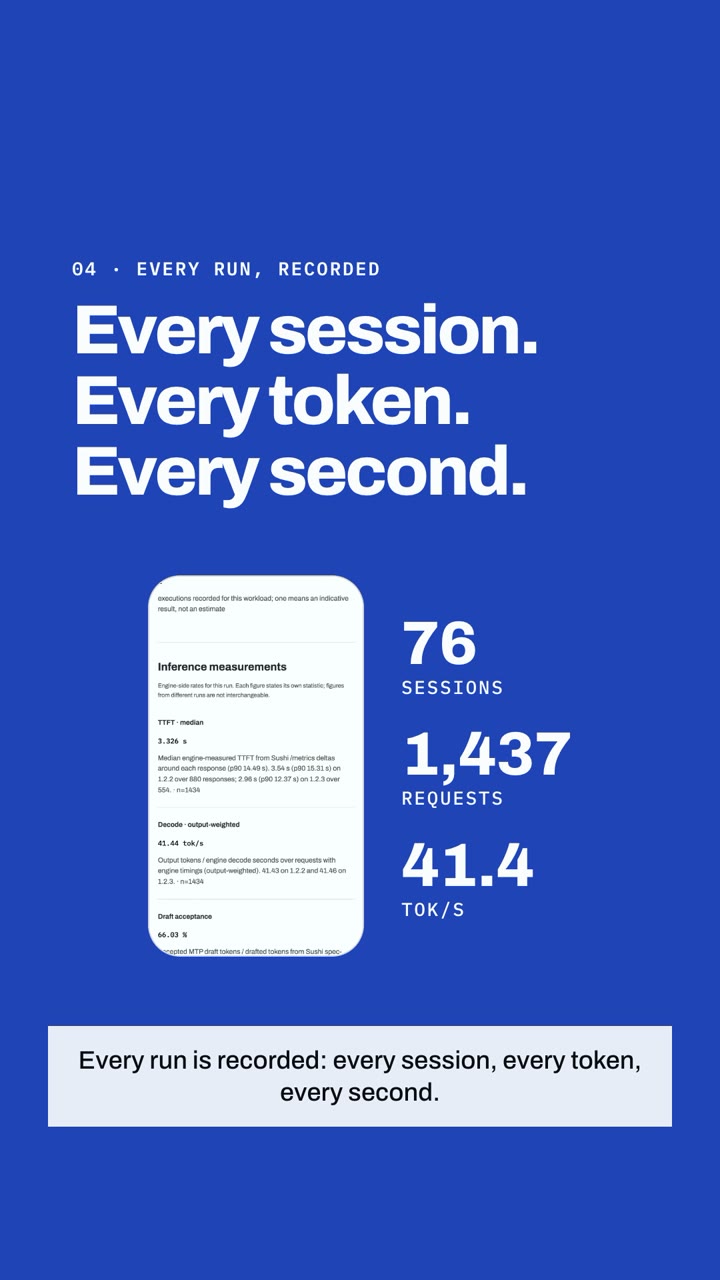
Scene 4 of the promo on the site's accent blue: the label EVERY RUN, RECORDED, the headline Every session. Every token. Every second., a run sheet in a phone frame beside the counters 76 sessions, 1,437 requests and 41.4 tok/s, and the caption
Local Model Benchmarks Promo · Sushi 1.2.4 · rendered video, scene 4

17–18 October 2026

Qwen 3.8 Flash Next

Sushi 1.2.4 (bf16 n-gram table) · Pi 1.1.0 + task-loop orchestrator

Session completed Local run

COMPLETE in 6 h 45 min with no operator action and 23 of 23 hidden acceptance cases. It follows the storyboard to the letter but reads like an animated slide deck, and the supplied laptop photograph is visibly AI-made.

Task requirements & full brief

The asset pack was made on the same Mac with local tools: site captures with headless Chrome, a figure built with the anatomy skill, photographs from Qwen-Image 2.1 and a VoxCPM2 narration. Renders are scored with hidden acceptance cases read from the video, including a background colour check per scene; taste is judged by a person.

  • Six scenes, each with its own background, a numbered label, a headline and footage, opening on its sentence of the narration.
  • The site's colours, Archivo and IBM Plex Mono type, framed footage with offset shadows and eased wipes.
  • Captions that stay on screen until the next sentence starts.
  • Real numbers from a recorded run, counting up, and a hidden-test score.
  • Offline, with six HyperFrames skills, including hyperframes-creative and hyperframes-keyframes.
How to read this comparison

Compare the generated builds and the checks recorded for each attempt. There is no normalised quality score, and the cloud task’s cumulative token totals and end-to-end rate include repeated context, reasoning, tool calls and waiting — they are not comparable with local per-request decode or prefill rates. The method page sets out which figures can and cannot be set against each other.